Simulated Tool Environments for Offline Agent Evaluation
Researchers are building realistic offline environments to test AI agents at scale.
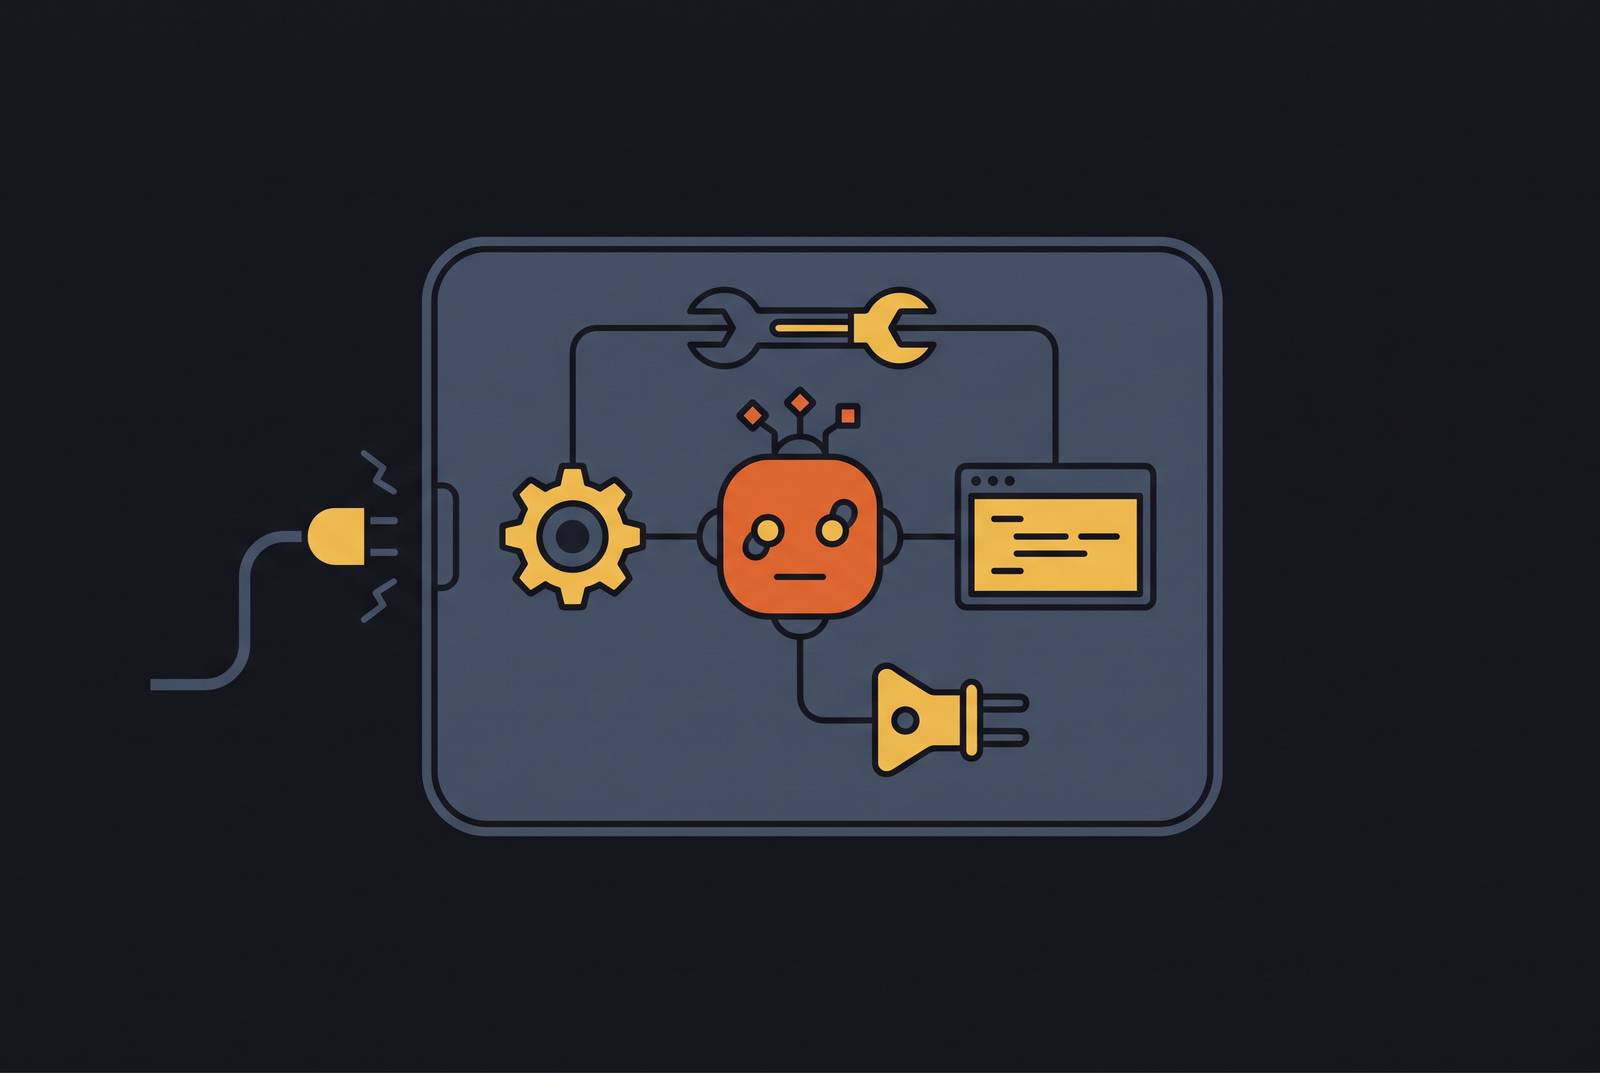
Simulated tool environments exist to solve a specific, practical bottleneck: agent evaluation needs volume and repeatability that live systems cannot give it. This piece walks through why real tool calls break down at scale, why the obvious fix (just have an LLM fake the responses) creates a worse problem, and how state-based offline simulation threads the needle, before turning to what such simulation can't tell you and what it takes to run one properly.
Evaluating agents against real tools at scale
An API key expires mid-run. None of this is exotic; it is just what happens when evaluation depends on live infrastructure someone else controls.
Running an agent against real tools during evaluation means routing calls through MCP services repeatedly, and that repetition adds up fast in both latency and cost. That instability collides directly with the two situations where evaluation matters most, large-scale agentic data generation and continuous integration pipelines, both of which demand runs that are fast and deterministic.
The scale involved is not a rounding error either. Agents have moved well past single function calls; a standard evaluation trajectory today runs past 60 tool calls, and in long-horizon settings like the UltraHorizon benchmark, past 400. Multiply that by however many trajectories a CI pipeline needs to check on every commit, and the live-tool approach stops being merely inconvenient. It becomes mathematically incompatible with how often evaluation actually needs to run.
Why LLM-simulated tool responses don't solve it either
The obvious patch is to skip the external service and have a strong (or fine-tuned) model generate a plausible tool response instead. It's a reasonable instinct. LLMs are good at sounding like an API. The trouble is that sounding like an API and behaving like one are different things entirely.
This isn't an argument against LLMs as evaluators. LLM-as-judge, scoring output quality against a rubric, is a different job and a defensible one. The failure mode below is specific to using generative text to stand in for stateful tool execution, which is a much stiffer requirement.
The core problem is hallucination in a very literal sense. A simulated tool response can look entirely plausible while corresponding to no actual underlying state at all. Ask an LLM to simulate a database lookup and it will happily return a record that never existed, formatted exactly like one that did. A second problem follows directly from the first: a non-reproducible evaluation is not an evaluation, it cannot live in CI, cannot be used to detect regressions, and cannot be compared across model versions. And an evaluation that can't be reproduced isn't really an evaluation. It can't sit in a CI pipeline, can't catch a regression, and can't be used to compare one model version against the next.
Multi-turn settings make this worse, not just inconvenient. A fabricated tool response in turn 2 corrupts every downstream step, and the agent may "succeed" on a trajectory that never corresponded to a real task. That's a nastier failure than an obvious crash, because it looks like a pass.
What state-based offline simulation is
The alternative that resolves both problems at once keeps the environment real while removing the live dependency. In state-based offline simulation, the environment is backed by an actual database or state file, and tool calls execute against that state directly, rather than reaching a live external service or asking a language model to invent what the response should look like.
Picture a test database seeded with a known set of customer records. When the agent calls a "look up account" tool, that call runs against the seeded database and returns whatever is actually there, no production system touched, no network hop to a third party. Recent work on this, AgentScaler from Tongyi Lab, builds environments exactly this way: each one is instantiated as a read-write database, and the tools available to the agent are executable code operating directly on that database's structure. The tool call is real code, doing real work, against real data. The only thing missing is the external dependency.
That distinction is the whole point of the word "offline" here. It doesn't mean fake. The word "offline" means no live service call happens during execution, while the computation and state mutation underneath the tool call are genuine. Its write still lands. Its error conditions still fire when the data doesn't support the request.
Constructing a scenario this way involves sampling a plausible sequence of tool calls from a domain-specific graph of what's possible, initializing the database to match the scenario, and grounding the whole thing in a coherent user intent so the trajectory reads as a real task rather than a random walk. Once built, the environment supports checking correctness two different ways: at the environment level, by comparing the final database state to the expected outcome, and at the level of individual tool calls, by checking whether each argument and response along the way was actually correct. That two-level check matters. An agent can reach the right final state through the wrong reasoning, and catching that requires looking at more than just the ending.
Why the multi-turn coverage problem defines simulation quality
Having a mechanism that produces trustworthy state is only half the story. Most benchmarks fall short of exercising that mechanism the way real agent behavior actually unfolds. τ-Bench and OdysseyBench are frequently cited as long-horizon evaluations, but measured against actual token counts and tool-call volume, they sit closer to short-horizon territory.
Real agent conversations don't look like single clean exchanges. Users ask clarifying questions. They circle back three turns later with a follow-up that depends on context from earlier. Agents make a mistake in turn four and have to recover from it in turn six. An evaluation that only scores one turn in isolation misses all of that, which is exactly why a simulated environment needs to treat the full conversation as the unit being evaluated, not the individual exchange.
This is not an academic concern. A 2025 preprint on multi-agent failures found that 17.14% of failures were step repetitions and another 13.98% were cases where the agent's stated reasoning didn't match the action it actually took. Both slip straight past a check that only looks at the final output, because the final answer can still be correct even when the path to it was broken.
UltraHorizon's numbers put the scale of the gap in perspective. Standard evaluation trajectories run past 60 tool calls. The heaviest long-horizon settings push past 400. At that volume, neither of the earlier approaches survives contact with reality: LLM-simulated responses would drift catastrophically across 400 tool calls, and real tool calls would be prohibitively expensive and slow. State-based simulation is close to the only approach that scales cleanly to that range.
But volume alone doesn't guarantee the simulation is any good. VISTA, out of Columbia and Arklex.ai, was built to measure exactly that gap: a six-metric suite scoring realism, capability coverage, and interaction effectiveness, aimed at telling whether a simulator is actually probing an agent's failure modes or just repeatedly confirming what it already does well. Its user simulator also blends UI-based and API-based interaction patterns, so evaluation isn't locked into one narrow style of how a user might engage the agent. Simulation quality is a thing that needs its own measurement, not an assumption you get for free once the mechanism is in place, and that premise matters more than the six metrics themselves.
Constructing environments at scale: the synthesis and diversity challenge
Knowing what a good environment needs to cover is one problem. Building enough of them is a separate, harder one. Assembling a reliable tool suite and a high-fidelity execution environment by hand takes real, sustained engineering effort, and that difficulty is the practical reason state-based simulation occurs far more often in evaluation than in training, where the volume of environments needed is an order of magnitude larger.
Training and evaluating agents both depend on trajectories generated by agents actually interacting with environments, and those trajectories are expensive to produce and genuinely hard to check for correctness. There's a direct relationship between how broad an agent's function-calling competence ends up being and how diverse the environments it trained and was evaluated against were. Narrow environments, unsurprisingly, produce narrow agents.
AgentScaler tackles this with programmatic synthesis: pull APIs from a broad collection, group them into coherent domains, then turn each domain into executable code running against its own database structure, all without a human hand-building each individual environment. EnvScaler pursues a similar direction, focused specifically on scaling tool-interactive environments through programmatic construction rather than manual curation. And a more recent proposal, Agent World Model, pushes the idea further still, describing "infinity synthetic environments" for agentic reinforcement learning, treating environment generation itself as a scalable systems problem rather than a one-off content task.
The practical upshot is straightforward even if the engineering behind it isn't: a simulated tool environment is only as good as the tool graph it's built from, and environments synthesized from broad, real API collections tend to generalize better than hand-picked scenario sets ever will. Coverage is a core requirement of the simulation approach, not an optional layer on top of it. It's the thing that determines whether the evaluation signal means anything.
What offline evaluation can and cannot tell you
None of this makes offline simulation a complete substitute for watching an agent operate in the real world, and pretending otherwise is where teams get burned. What offline evaluation is genuinely good at: reproducibility, catching regressions, and fitting cleanly into a CI pipeline. It answers one specific question well, which is whether the agent got worse on the tasks it was already being checked against.
What it can't do is anticipate what hasn't shown up yet. A held-out test set assembled last month has no way of knowing about a conversational drift pattern that starts happening in production next week, or a tool failure mode that only occurs against a live system's actual load conditions. These constraints make real-environment evaluation impractical for the two use cases that need it most: large-scale agentic data generation and continuous integration pipelines where runs must be fast and deterministic.
There's also a statistical trap. Plenty of standard agentic benchmarks reduce what is fundamentally a stochastic process down to one leaderboard number from a single run, and the confidence interval on that kind of sample is often wide enough that it can't reliably tell a genuinely good agent apart from a mediocre one. One run, one score, and a false sense of precision.
So where does confidence actually come from? Not from the offline suite alone. Detecting distribution drift and catching failures no one wrote a test for requires monitoring the agent after it ships, including systematic human review of what it's actually doing in production. That's the recommendation in Anthropic's 2026 guidance on evaluation practice, and it lines up with how most mature evaluation pipelines are actually structured. Offline and online evaluation aren't competing approaches; they answer different questions and sit in different parts of the pipeline. Offline belongs in CI, catching regressions before they ship. Online belongs downstream, watching real traffic for the drift and the novel failures that a test suite, by definition, could never have anticipated.
Evaluation frameworks that implement offline simulation in practice
A handful of platforms have built out this thinking into actual tooling, each with a different center of gravity.
MLflow supports Ragas, DeepEval, Arize Phoenix, TruLens, and Guardrails AI as native pluggable scorers. Ragas specifically started life focused on RAG-specific metrics and has since broadened into agent evaluation more generally.
Galileo positions itself as an observability and evaluation platform spanning offline evaluation, production monitoring, and runtime guardrails in one system, and its distinguishing piece is Luna-2, a set of small language models built specifically for evaluation tasks rather than general-purpose generation, which brings the cost of running evaluation frequently down considerably.
LangSmith, LangChain's commercial platform, offers several evaluator types (human, heuristic, LLM-as-judge, and pairwise comparison), supports trajectory-level agent evaluation, and runs both offline and online evaluation inside the same platform.
Arize extends its background in ML monitoring into LLM and agent evaluation through a commercial product, Arize AX, and an open-source framework, Phoenix. Its tracing is OpenTelemetry-native, covering frameworks like LangGraph, LlamaIndex, DSPy, and CrewAI, using OpenInference semantic conventions built on top of OpenTelemetry. Arize counts Uber, PepsiCo, and Tripadvisor among its customers and is backed by a $70 million Series C.
Augment Code's Cosmos takes a different angle on the problem entirely. Rather than competing on evaluation metrics directly, it addresses what happens after an evaluation surfaces a failure, turning a one-off fix into shared, team-wide memory so the same failure doesn't get rediscovered from scratch by someone else next month. It's positioned as an orchestration platform running agents across the full development lifecycle, with persistent context and reusable Experts.
None of this is a competition with one winner. The AlphaEval paper finds that production agent evaluation averages 2.8 distinct leaf-node evaluation types per task. That number says something important on its own: no single platform covers every dimension an agent evaluation actually needs, and most teams end up running two or three tools together rather than picking one.
What the execution environment underneath the simulator must provide
All of the framework-level thinking above rests on an assumption that's easy to overlook: the sandbox running the simulation is trustworthy. If it leaks state between one test run and the next, results stop being reproducible, which defeats the purpose of building an offline environment. If it shares a kernel with other workloads on the same host, an agent trajectory that goes sideways can do more than fail its own test.
Because tool calls in offline simulation are executing real code against real state, that code has to be treated as untrusted, the same way any external input would be, and run somewhere genuinely separated from the rest of the system. Standard containers don't clear that bar on their own, since they share the host kernel, and a malformed or adversarially shaped tool call can, in principle, escape the simulated boundary and touch the underlying machine. The response the infrastructure world has settled on is layered: microVMs like Firecracker, or microVM-backed runtimes like Kata Containers, for workloads that need a dedicated kernel and the strongest possible isolation; gVisor where syscall interception is enough without the overhead of a full virtual machine; hardened containers reserved for code that's already fully trusted.
Speed is not a secondary concern here either. If provisioning a simulation environment takes several seconds per episode, that cost multiplies across every trajectory in a CI run, and cold-start latency quietly becomes the thing deciding whether simulation is practical to run on every commit at all. Sub-second provisioning isn't a luxury feature; it's closer to a baseline requirement for the approach to work at CI speed.
Statefulness across turns matters just as much for multi-turn simulation specifically. An environment that resets itself after every single turn can't represent the accumulated state that defines what a realistic agent trajectory even looks like, so the sandbox needs to hold state persistently within an episode and restore it cleanly between episodes. DeltaBox, a 2026 paper on scaling stateful agents, addresses this directly with millisecond-level checkpoint and rollback for sandboxes, letting large numbers of simulation episodes run without paying the cost of fully reinitializing the environment each time, avoiding the overhead that would otherwise make the whole approach fall over at scale. That's not a minor optimization. At the volumes long-horizon evaluation demands, full reinitialization per episode is exactly the kind of overhead that makes the whole approach fall over.
How purpose-built agent runtimes address the simulation infrastructure problem
Agents have stopped looking like short-lived, stateless function calls, one input in and one output out. The direction of the field is toward multiple coordinated agents running continuously, holding context over long stretches, reaching for external tools repeatedly, and communicating with each other across extended periods. Simulation infrastructure that was built around the older assumption, brief and disposable, doesn't map cleanly onto that reality anymore.
A runtime built for this world from the ground up needs the isolation guarantees, the fast provisioning, and the persistent, checkpointable state covered above, not bolted on as an afterthought but treated as the foundation the simulator sits on. The fidelity of any evaluation is capped by the infrastructure underneath it. A simulator can implement every principle described here, real state, verifiable outcomes, wide tool-graph coverage, and it will still only be as trustworthy as the sandbox actually executing the code. Any evaluation number that comes out the other side is only as trustworthy as that layer.
Sources
- Towards General Agentic Intelligence via Environment Scaling
- VISTA: A Versatile Interactive User Simulation Toolkit for Agent Evaluation
- Best AI Agent Evaluation Tools for Production Teams (2026) | Augment Code
- ULTRAHORIZON: BENCHMARKING AGENT CAPABILI
- Top 5 Agent Evaluation Tools in 2026 | MLflow
- Democratizing Tool Learning with Environments Fully Simulated by a Free 8B Language Model
- EnvSimBench: A Benchmark for Evaluating and Improving LLM-Based Environment Simulation
- Top 5 AI Agent Evaluation Platforms in 2026